

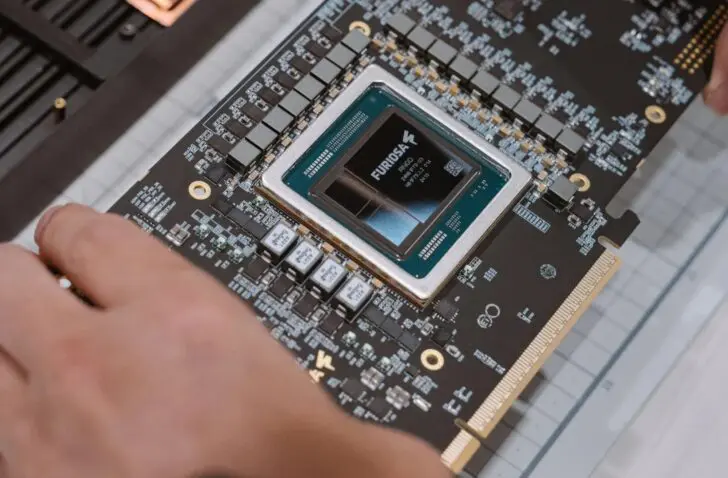
FuriosaAI is partnering with Broadcom to develop a third-generation AI accelerator. The new chip will feature a chiplet architecture with a 2 nm compute component, HBM4/4E memory, and Broadcom networking technology.
FuriosaAI announces a new AI accelerator in collaboration with Broadcom. This marks the company’s third generation of AI chips. The new accelerator builds on the existing architecture but evolves into a chiplet-based design. FuriosaAI is targeting large AI clusters at hyperscalers.
Key role for Broadcom
Broadcom plays a major role as a result. The company provides not only packaging but also Ethernet, PCIe, and switching technology.
FuriosaAI combines a 2 nm compute chiplet with HBM4/4E into a single system-on-chip (SoC). Broadcom will use its packaging technology to integrate these various components into a single platform built for inference.
The chip succeeds two previous generations of accelerators. The first chip was optimized for computer vision. The second generation was named RNGD and was marketed for AI inference for enterprise customers.
Inference engine
With the new accelerator, FuriosaAI aims to build another inference engine tailored for high token volumes in large AI environments. This involves more than just raw computing power: efficient data movement between servers and racks is equally important. Both companies intend to scale AI clusters to thousands of nodes. The infrastructure must ensure fast communication within large inference clusters.
The chip is optimized for real-world AI workloads, including intensive post-training sampling. FuriosaAI states that its data-movement-focused approach is more efficient than the threading approach used by GPUs, aiming for higher performance per watt and greater token density.